If your AI team is maxing out premium-model quotas before day seven, that's not just a token problem.
It's a unit economics and architecture problem.
You probably need to rethink your model-routing strategy.
In my own stack, ChatGPT Pro + Ollama is the most practical combination. I push Luna and DeepSeek V4.1 hard for development, distillation, and detached-system builds-while the higher-tier models mostly come in for final audit, validation, and direction.
In one month, I shipped 25 detached systems, nearly half already app-based, and my development cycle is now roughly 3× lebih pantas.
I also built an AI agen with smart routing, plus a web-based CLI and Telegram protocol.
Total AI operating cost? Tentang RM200/bulan only.
And not just for development. AINNA staff use the same stack for daily work, including generating thousands of images every week.
So the interesting part isn't just lower AI cost.
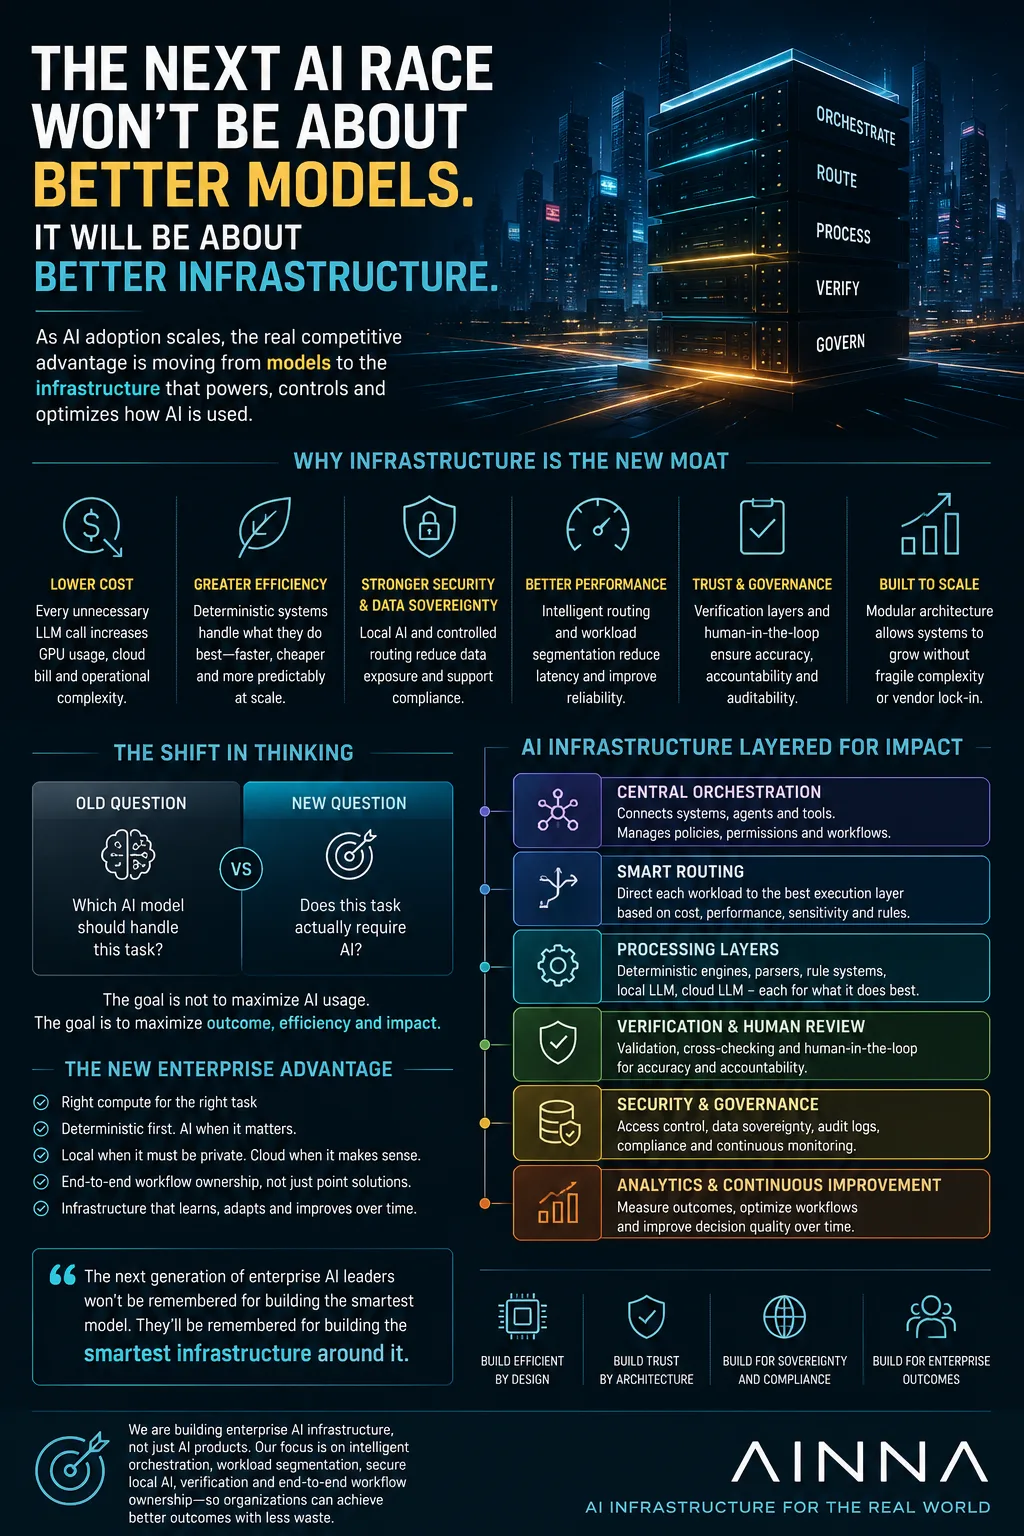
It's what happens when model routing, internal agents, and detached systems become your own infrastructure-instead of depending on one expensive model for everything.
Maybe tokens aren't tired anymore. The GPUs are the ones fed up watching us. Ha ha ha.
Match the right model to the right workload. Reserve the strongest model for audit and direction, and turn repeatable intelligence into infrastructure you own.


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
Di sini baru 2 nampak masuk akal.
The framing around chatGPT pro + ollama is better than I expected.
Whoever wrote this actually did the work on jumlah AI operating cost.
The case for it's what happens when model is well made.
Worth reading for including generating thousands of images alone.