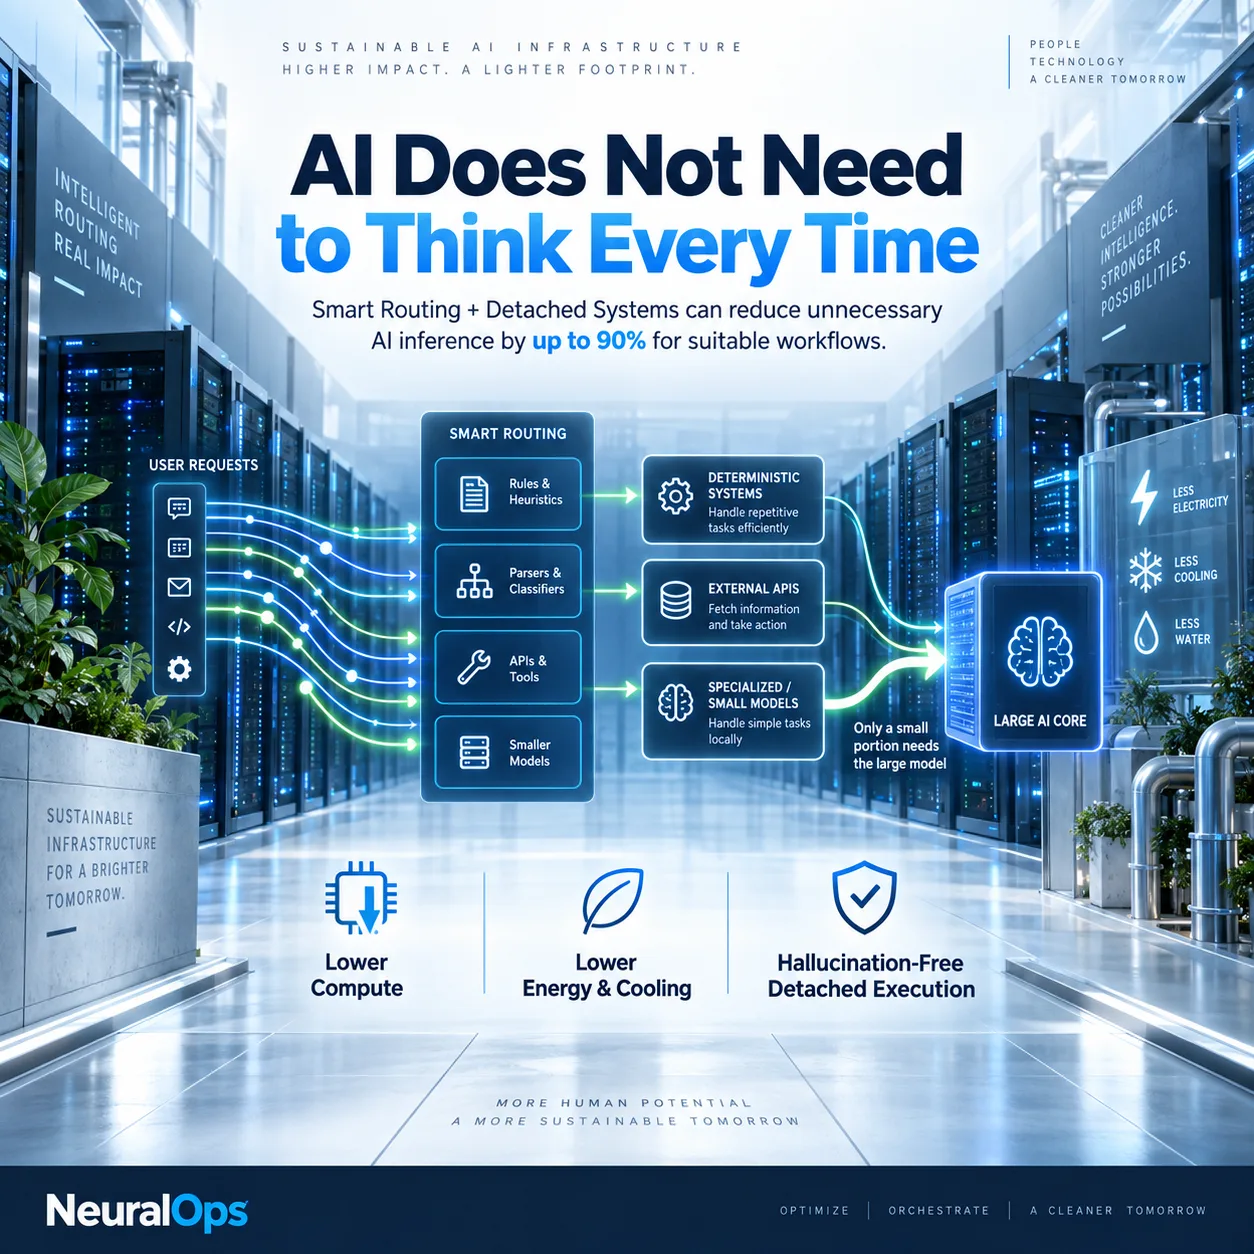
AI infrastructure is growing fast, but there is a financial side we cannot ignore: electricity, cooling and water consumption.
Penyelidikan indicates that after deployment, inference can consume as much as 80–90% of an AI model’s jumlah energy. Each avoidable LLM call drives up GPU usage, electricity bills, heat generation, and ultimately cooling expenses-all of which erode profit margins.
That’s why we’re building NeuralOps on a core financial principle:
Not every business operation requires a full LLM.
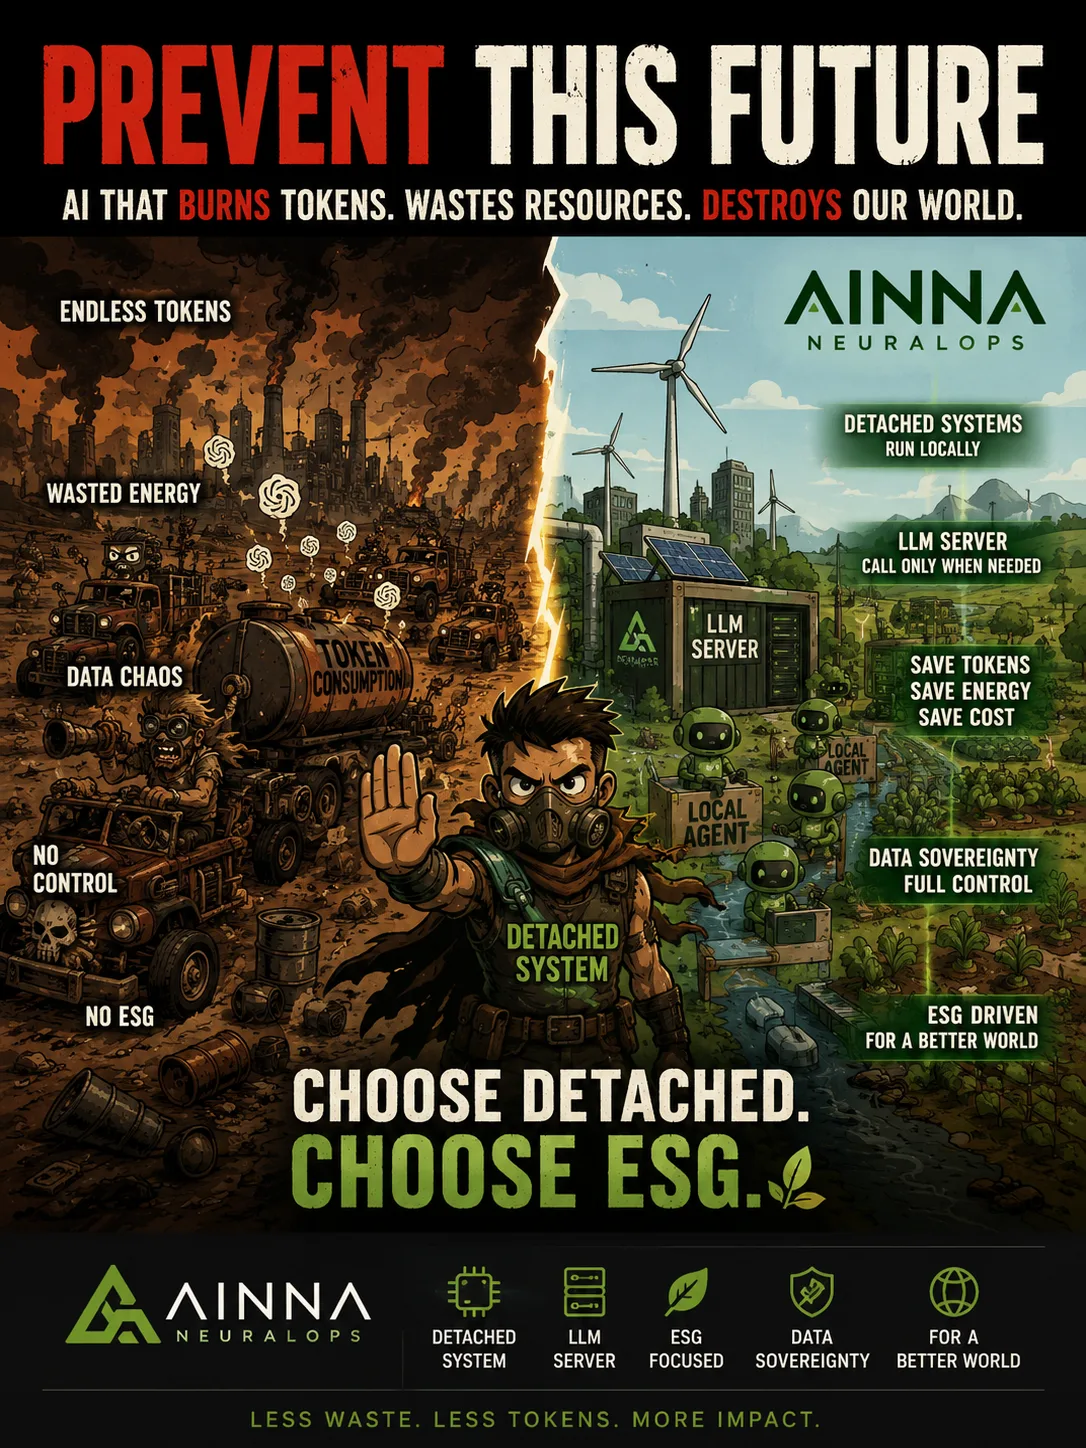
With Smart Routing, we direct tasks to the most cost-effective option-rules, parsers, databases, APIs, or lebih kecil models-before ever escalating to heavy LLM reasoning. Once a process stabilises, we can lock it into a detached deterministic system that runs repeatedly without triggering an LLM call.
For repetitive workflows that fit the pattern, this architecture can cut AI inference demand by up to 90%-a direct reduction in compute costs.
The financial impact goes far beyond token costs.
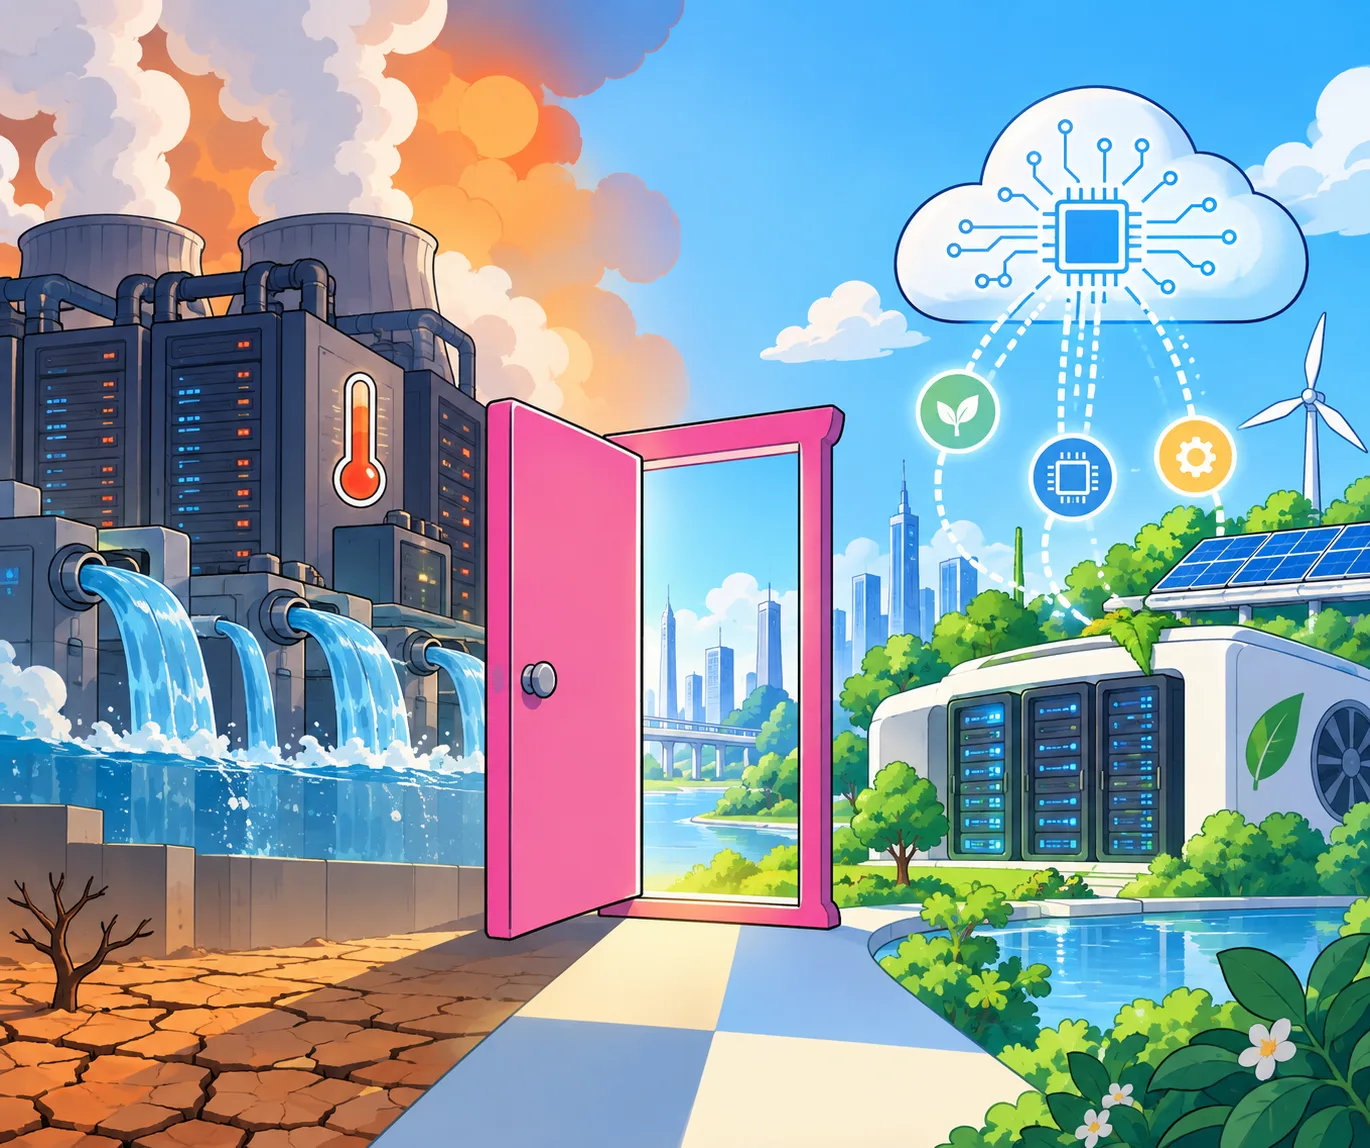
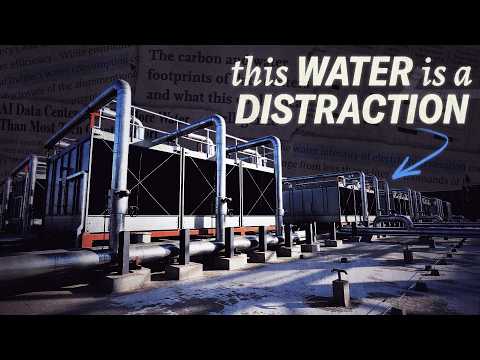
Less inference → Less GPU compute → Less electricity → Less heat → Less cooling → Lower water demand. That’s a measurable impact on your operating expenses.
Kebolehpercayaan is another financial benefit.
With a detached workflow, execution no longer relies on an LLM, which means zero token consumption and zero hallucination risk on that path. We deploy intelligence where reasoning is critical, and deterministic systems for repetitive tasks-reducing both operational risk and unexpected cost.
We believe sustainable AI isn’t just about building greener data centres.
It’s also about stopping unnecessary AI inference from ever hitting the data centre-and your electricity bill.
That’s the philosophy behind NeuralOps:
use AI when intelligence is required, and deterministic systems when it isn’t.
#ArtificialIntelligence #AgenticAI #NeuralOps #SovereignAI #GreenAI #SustainableAI #DataCentre #AIInfrastructure #SmartRouting #Automasi #PKS


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. Nama dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
The part on AI infrastructure is growing fast is the bit I keep re-reading.
Not convinced on that’s a measurable impact yet, but fair argument.
We hit much as 80–90 90% at work before. Good that someone wrote it down.
This is where parsers, databases, APIs, or lebih finally makes sense.
Short and clear. as much as 80 is worth sending to my team.
Still thinking about inference can consume.
Useful. We are dealing with which means zero token consumption right now. Worth reading twice.
Honestly execution no longer relies caught me off guard.
Already sent this to two people. electricity, cooling and water is why.
I read this twice. Once a process stabilises is the part that stuck. Have a few questions left here.
electricity bills, heat generation - that is the whole thing in one line.
Not sure I agree with cost-effective, but the rest holds up.
First piece I have read that treats to 90%-a direct 90% honestly.
The numbers around which means zero token consumption make more sense than most posts I read. Worth reading twice.
I would push back slightly on cost-effective, but the direction is right.