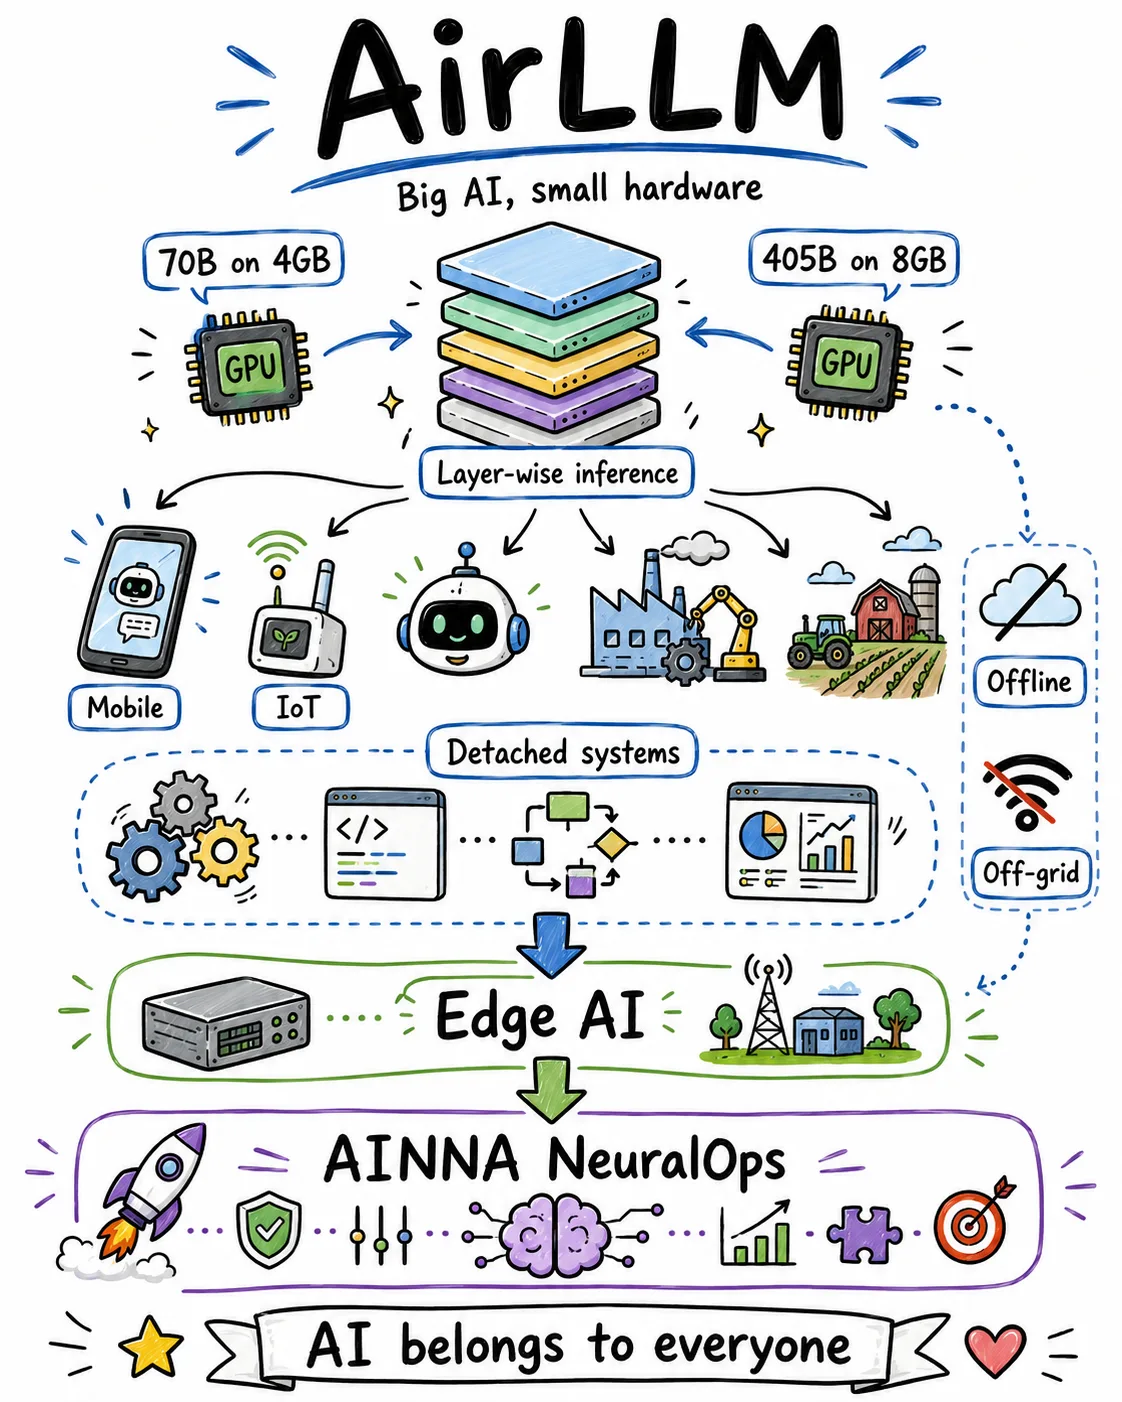
AirLLM may become one of the biggest shifts in how we think about AI infrastructure.
You can now run a 70B model on just a 4GB GPU and even scale up experiments toward the massive Llama 3.1 405B using only 8GB VRAM - that is not just hype, that is a serious architecture shift.
For years, powerful AI felt like it belonged only to big tech, hyperscalers, and companies with monster GPUs, huge cloud budgets, and data center access. Everyone else was basically renting intelligence by the token.
But that story is changing fast. With layer-wise inference, smarter memory handling, and open-source innovation, large models are becoming more accessible to normal builders, PKS, students, researchers, and local tech communities.
The real permainan changer is not only bigger models. It is how we run them - lighter, smarter, more local, more efficient, and more practical for real-world use.
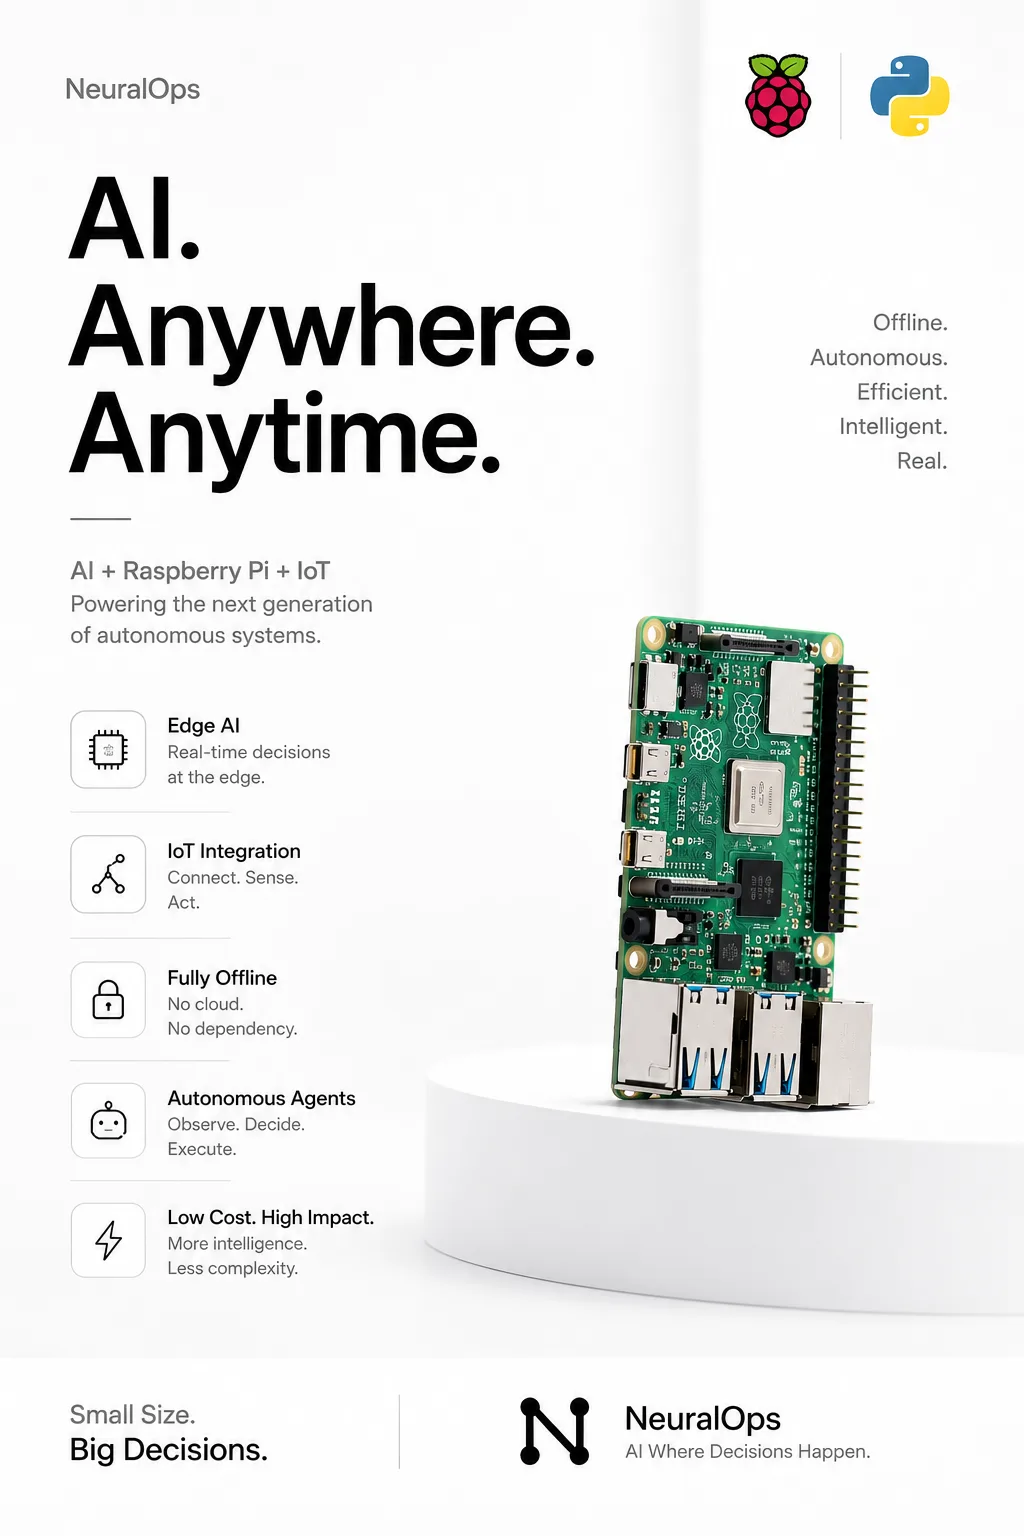
This is where Edge AI and AINNA NeuralOps come in. Instead of depending fully on cloud AI, intelligence can move closer to the device, the sensor, the machine, the farm, the factory, and the actual operation on the ground.
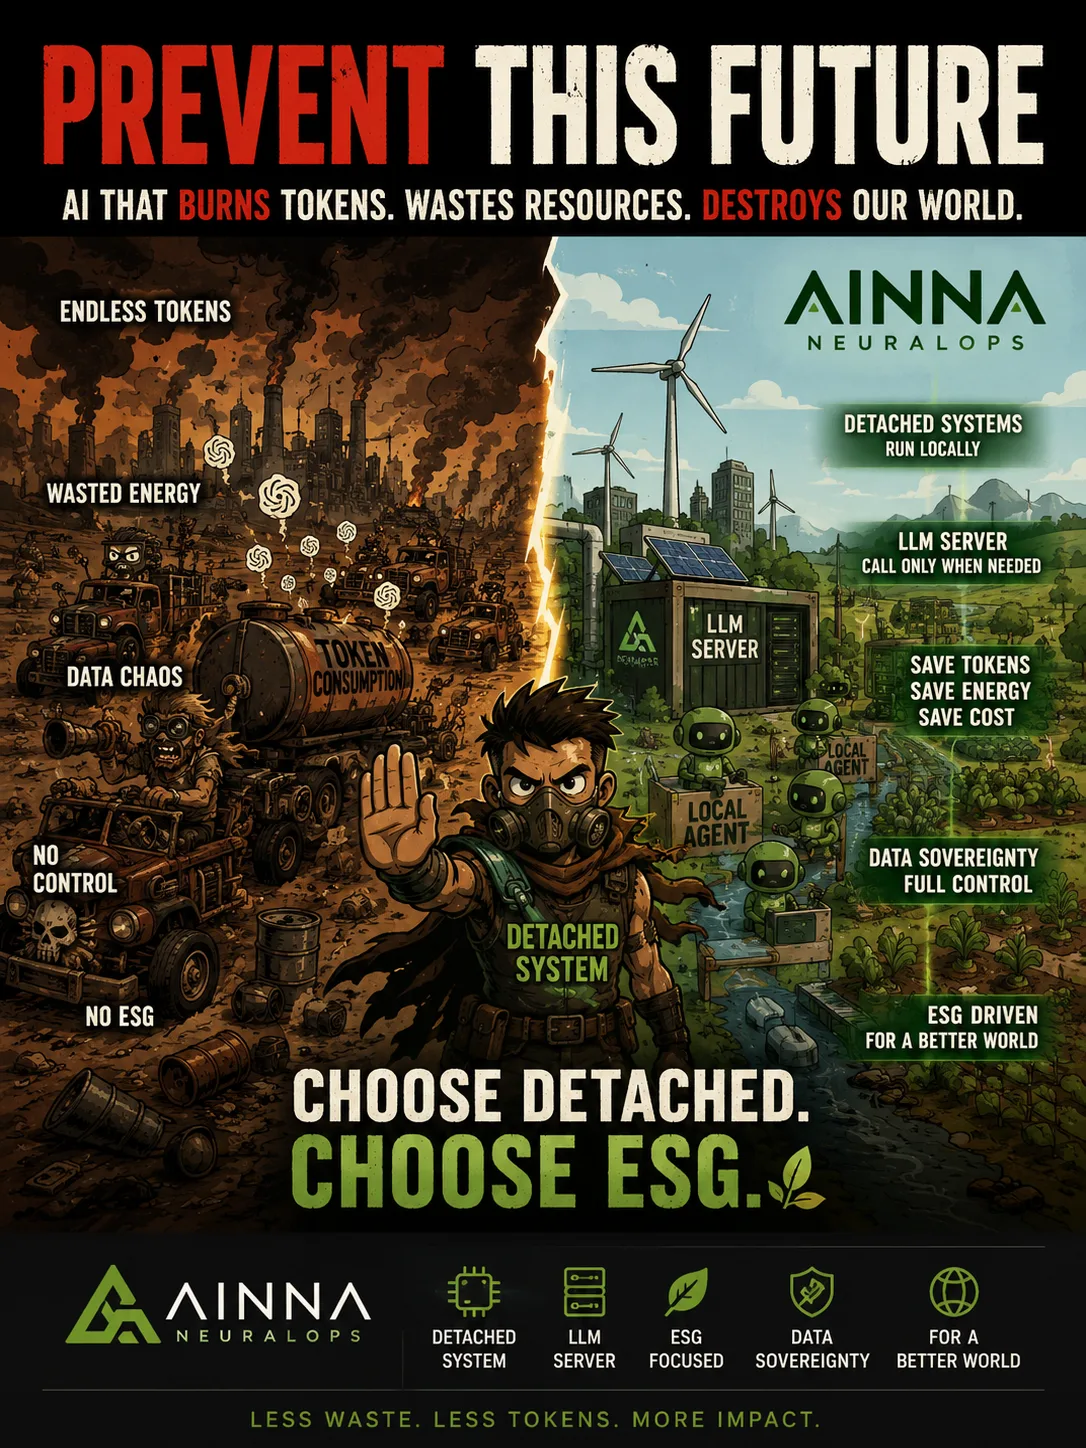
Combine this with detached systems, and the impact becomes even stronger. Let the LLM plan, audit, generate, and decide - then let local scripts, dashboards, cron jobs, APIs, sensors, and automation systems continue the work without burning tokens 24/7.
Soon, mobile devices and IoT systems will have their own small LLM models running offline and off-grid. This is the AI future I believe in: lighter, smarter, local, practical, and genuinely for everyone - not just hype, not just cloud dependency, and definitely not only for big tech.


Ruang pembaca
Apa pendapat anda?
Komen baharu dihantar untuk semakan terlebih dahulu. Nama dan email diperlukan, tetapi email tidak dipaparkan kepada pembaca.
Sent this to two people already. hyperscalers, and companies with monster is why. Have a few questions left here.
अगर 70B पर अगला लेख आए तो मैं ज़रूर पढ़ूँगा।
The numbers around burning tokens 24/7. 24 make more sense than most posts I read.
Worth reading just for massive llama 3.1 405B.
You can tell the writer actually worked on now run a 70B.
Short and clear. tokens 24/7. soo 7 is worth sending to my team.
Angka soal 70B lebih masuk akal daripada kebanyakan artikel.
Not sure I agree with huge cloud budgets, and data, but the rest holds up. Have a few questions left here.