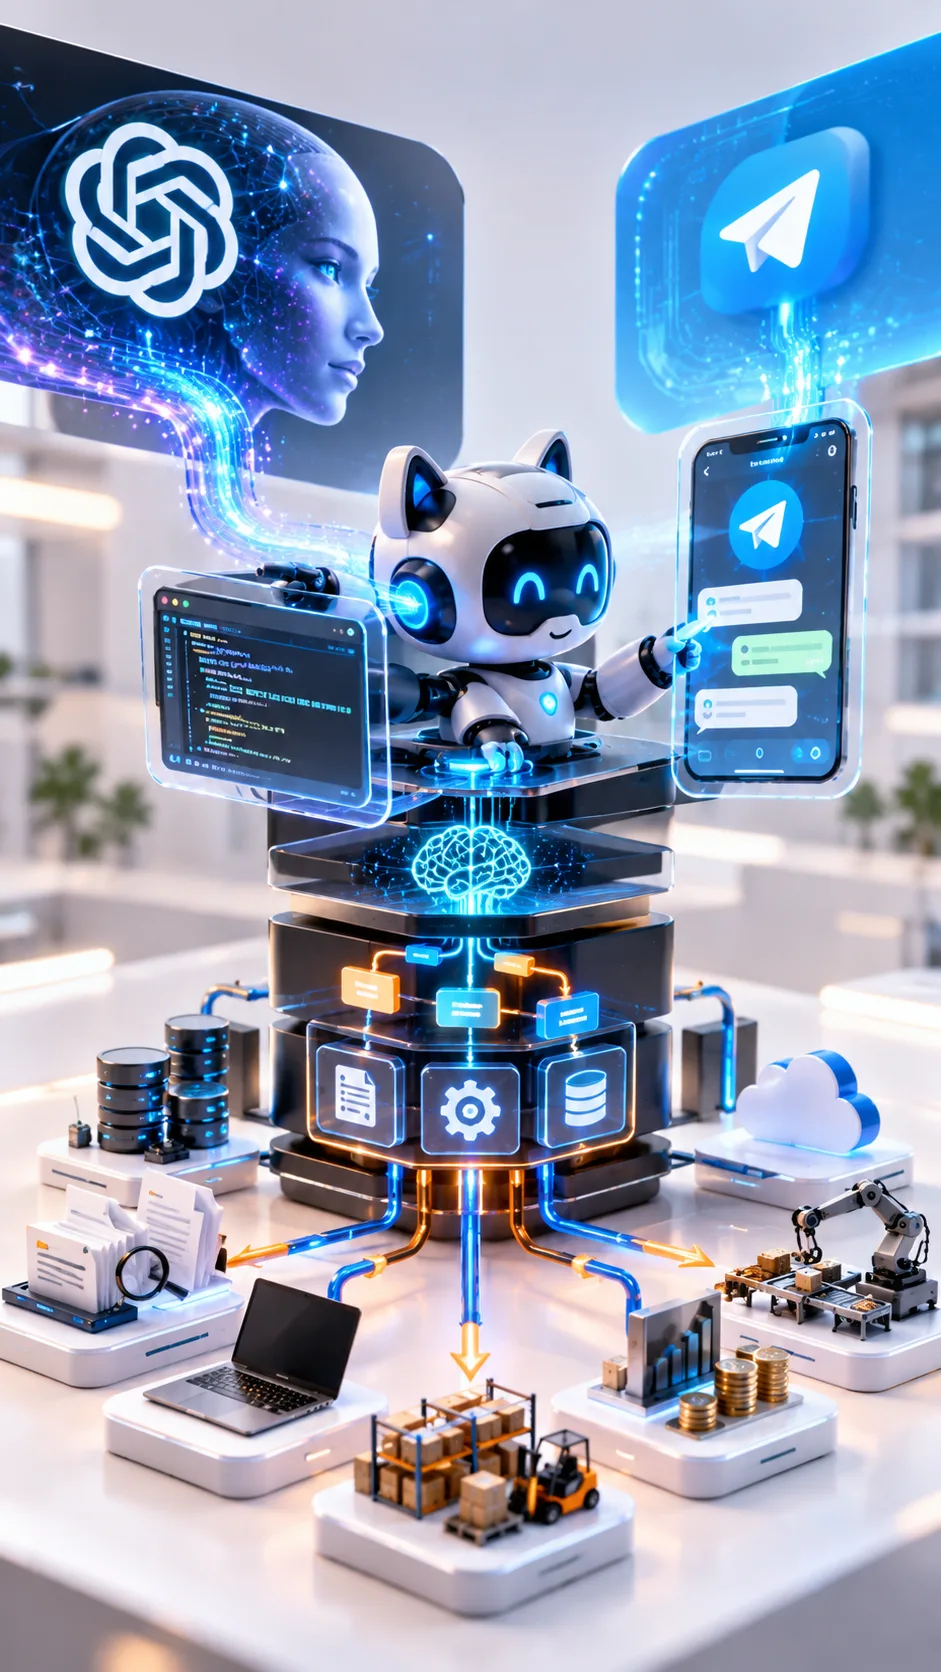
OpenAI's latest direction around AI agents matters to me less as a product announcement and more as confirmation of something we've been dealing with at the systems level for a while now. The question in the field is no longer which model reasons best. It's how that reasoning gets routed, executed, retried, logged and wired into operational systems that have to keep running. The model still carries weight - but everything around it carries the same weight now.
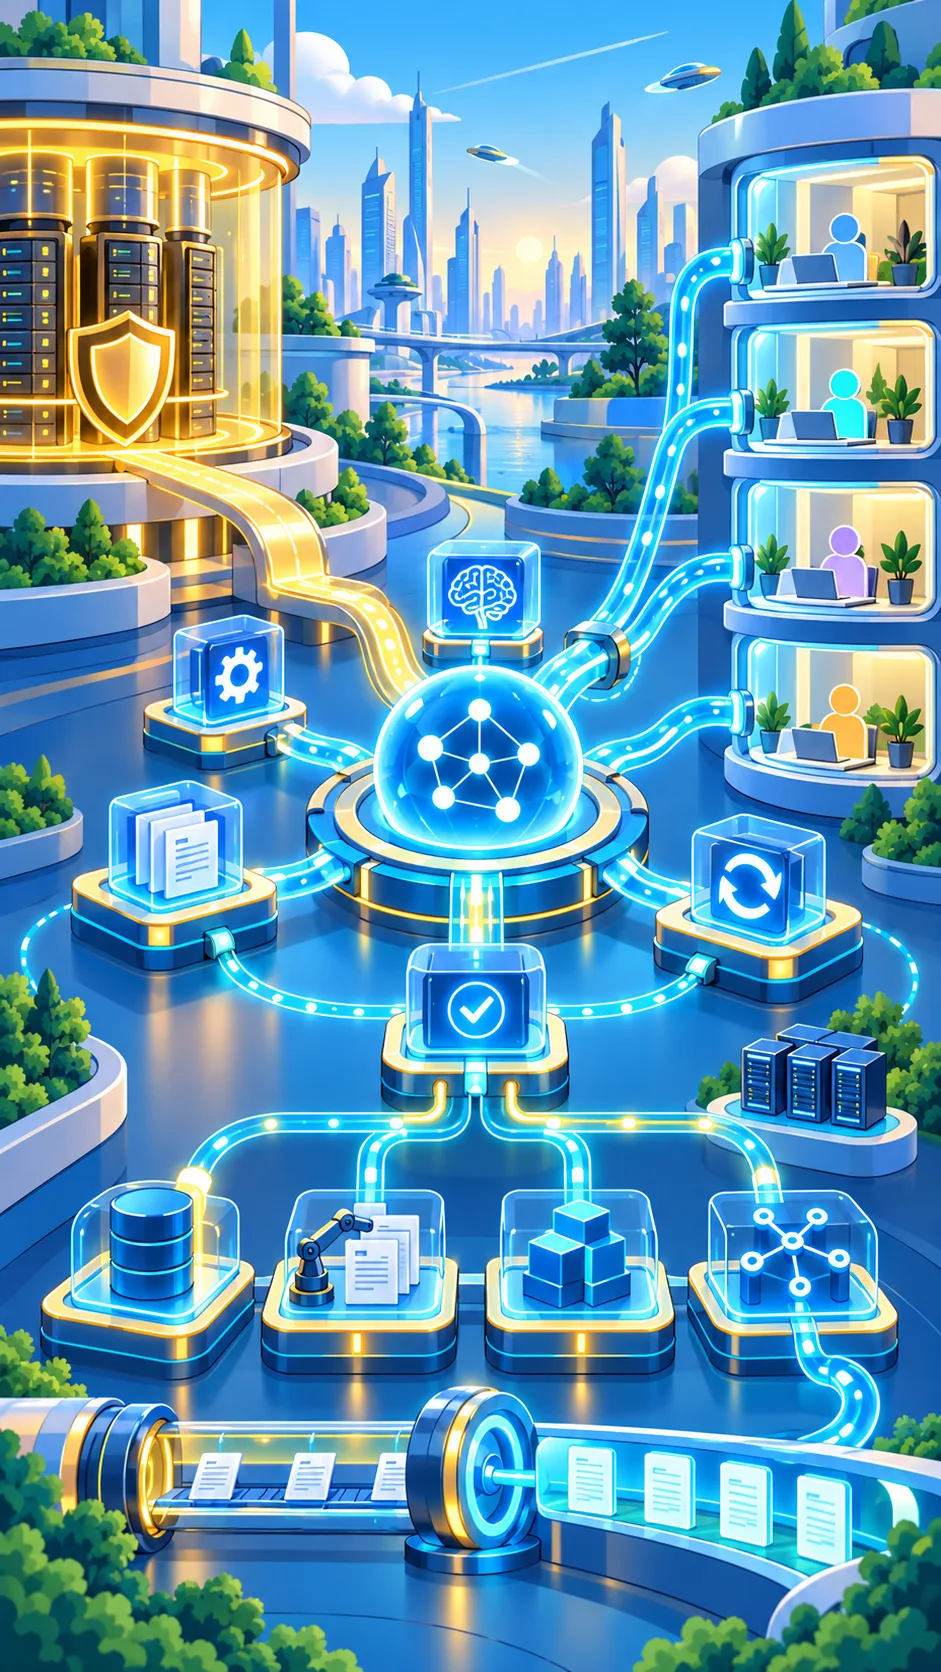
That's essentially the shape of what we build with AINNA NeuralOps. I don't leave tasks parked inside a continuous LLM loop; that's how you burn tokens and latency on work that never needed a model looking at it. NeuralOps splits the stack into explicit operational layers instead. The model handles reasoning when reasoning is actually called for. The smart routing layer, specialised parsers, detached services, APIs and databases handle the deterministic execution path.
One thing I push hard on is making the agen more Web CLI-friendly. Operators need to see what the agen did, replay a command, inspect state, patch a rule - not sit in a chat bubble waiting for a paragraph back. A Web CLI gives you a real operational surface: it's inspectable, it's scriptable, it's troubleshootable, and it drops into existing workflows instead of asking the workflow to move.
I've extended that same interaction layer out through Telegram as well. The reasoning is straightforward - the agen shouldn't be trapped behind a single dashboard. Commands come in from a messaging client people already have open, while the routing, execution and automation stay inside NeuralOps. That's the same interaction pattern you see in ecosystems like Hermes and OpenClaw, where messaging and command surfaces become part of the operating model rather than a demo skin.
The architectural principle I keep coming back to is this: not every task requires continuous AI reasoning. A stock update, a database sync, a scheduled job, an API transaction, a validation rule - none of those need a model deliberating over them on every single pass. Once I've mapped the workflow, deterministic code runs it lebih pantas, more consistently and at a fraction of the cost. The LLM gets called when there's genuine ambiguity, an anomaly, interpretation work, or a higher-level decision to make. Everything else stays on rails.
That's why I don't read the next phase of agentic AI as a race to build bigger models. The competition moves to orchestration, execution, observability, integration and cost per operation. OpenAI is pushing that transition from the platform side. We're attacking the same problem from the field side - deployments for real PKS, on real budgets, with real operational constraints and real people running them.
The model supplies the intelligence. The stack is what turns that intelligence into operasi.
#AINNA #NeuralOps #AgenticAI #AIAgents #OpenAI #AIInfrastruktur #Automasi #WebCLI #Telegram #DigitalTransformation


Ruang pembaca
Apa pendapat anda?
Komen disemak sebelum diterbitkan. Email diperlukan untuk moderasi dan tidak dipaparkan kepada pembaca.
Kalau ada lanjutan tentang it's how that reasoning gets, saya pasti baca.
First piece I have read that treats that's essentially the shape honestly.
พูดตรง ๆ เนื้อหานี้ ก็น่าสนใจ
Malinaw ang paliwanag tungkol sa artikulong ito at madaling sundan.